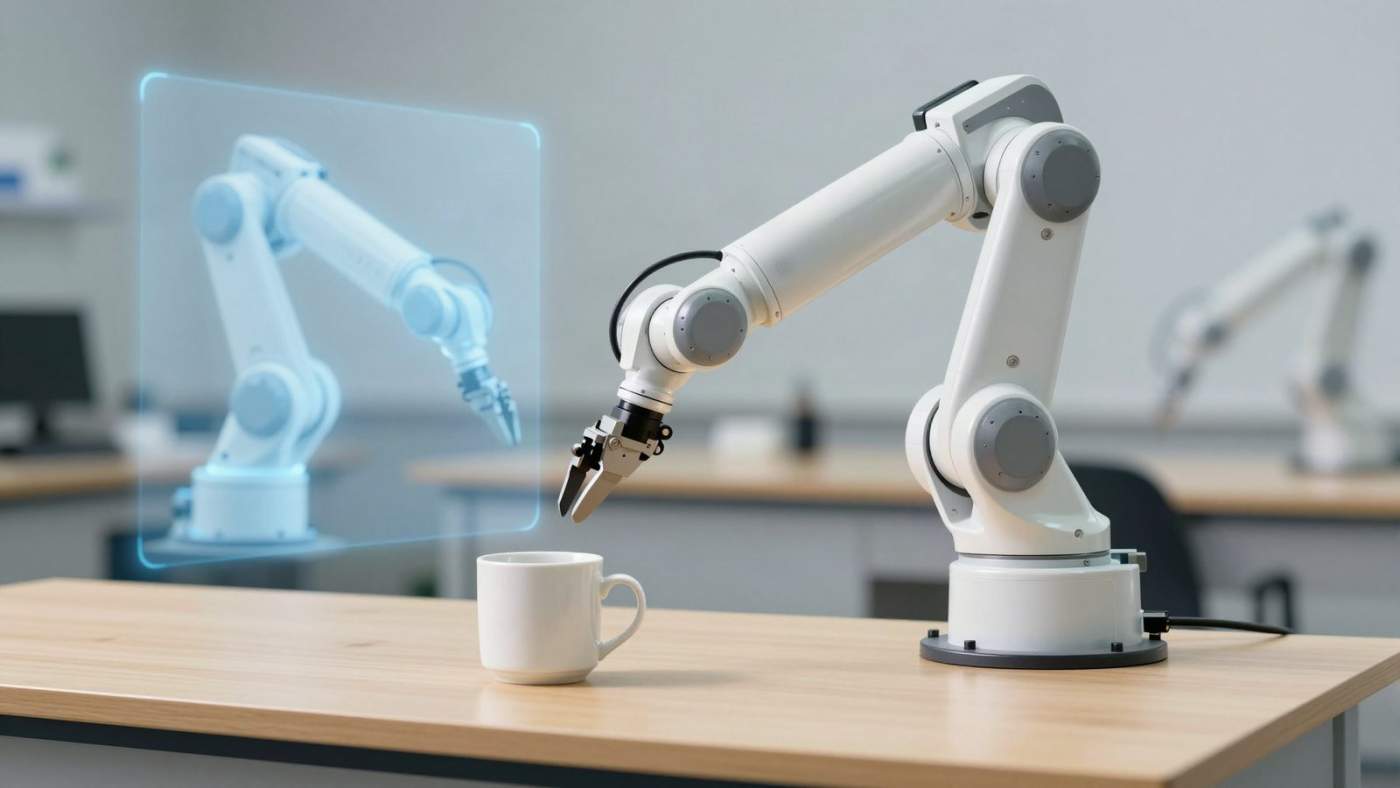
Runway Praxis-1 has been openly available since November 11, 2026: the robotics model from video specialist Runway ships with open weights under the Apache 2.0 license, including inference and fine-tuning code, and explicitly for commercial use as well. Praxis-1 is a so-called world action model with 27 billion parameters that learns from video how objects behave and turns that into control commands for robots. Most of the performance figures come from Runway itself.
What Runway Praxis-1 is
Runway introduced Praxis-1 in September as its first world action model and has been testing it with partners since. According to the release announcement, Noble Machines, Standard Bots and Ultra ran it on a legged humanoid, a six-axis industrial arm and a dual-arm warehouse robot. Since November 11, the same model is available to every developer and researcher.
The core idea: real robot data is scarce and expensive, while video exists in huge quantities. According to Runway, a model that has learned to predict video already knows a lot about how hands move and what a task looks like halfway through. Praxis-1 therefore predicts both at every step: what the scene will look like next and which motion gets it there. Unlike classic vision-language-action models (VLAs), video prediction sits at the centre.
Architecture and hardware needs
Runway’s technical report describes three parts:
- Video backbone: a mixture-of-experts diffusion transformer with 26.9 billion parameters. About 2.8 billion parameters are active per token; each MoE layer has one shared expert and 128 small routed experts, of which each token picks eight.
- Action expert: a small 16-layer transformer with about 314 million parameters that reads the predicted video features and computes motions from them.
- Robot-specific projections: thin input and output layers per robot type, so one model can control different arms and platforms.
Each call returns 24 action rows at 15 Hz, or 1.6 seconds of motion. In total the model has 27.2 billion parameters and takes up about 54.4 GB in bf16; according to the report it runs on a single GPU with 80 GB of memory. On a single H100 server, a call in the default mode takes about 0.52 to 0.55 seconds of server time, and about 0.12 to 0.13 seconds with an optional real-time chunking mode. In the announcement, Runway also lists workstation cards such as the RTX 5090 and RTX PRO 6000, as well as Jetson Thor on the robot itself. How much performance remains on smaller cards is not quantified in the documents we read.
Three checkpoints are available on Hugging Face: a model fine-tuned on the DROID dataset for single-arm Franka robots, a variant for the bimanual YAM robot and the base model without robot-specific heads as a starting point for your own adaptations. On top of that come code on GitHub, LeRobot support, integration in vLLM-Omni and hosted inference. The frozen components, a Wan2.2 VAE and the Qwen3.5-2B text encoder, are distributed separately under their own licenses.
Benchmarks: strong among open models, not the overall leader
Runway highlights NVIDIA’s RoboLab-120 leaderboard. According to the company, Praxis-1 reaches 46.2 percent success across 1,200 episodes there, ahead of FLUX 3 Action at 42.9, Cosmos3 Nano at 36.8 and π0.5 at 28.0 percent. That makes it, according to Runway, the best world action model and the best open robot foundation model on that list.
The technical report, however, also states what the press release leaves out: the top two places on the RoboLab-120 leaderboard belong to LLM agents with 86.0 and 57.1 percent. Large multimodal models control robot arms there through tool or code interfaces. Runway argues these agents are too slow and too expensive. In its own comparison on the same YAM station with three tasks, GPT-6 Astra took 15.6 times longer on average and cost 51 times more per completed task. That is a vendor comparison with a very small sample.
More figures from the report:
- Real Franka arm: on the ten published FLUX 3 Action tasks, Praxis-1 succeeded in 88 of 100 episodes in a test run by Positronic, FLUX 3 Action in 80.
- Unseen robot: fine-tuned on Google’s RT-1, which did not appear in the training data, Praxis-1 reaches 80.0 percent on the SimplerEnv benchmark versus 52.4 percent for the original RT-1 policy. According to Runway, fine-tuning took about 28 hours on 32 H100 GPUs.
- 4-bit variant: with experts rounded to NVFP4, the model scored 46.5 percent (279 of 600 episodes), the bf16 version 47.8 percent. Runway considers the difference not significant.
Limits Runway names itself
The section on weaknesses is refreshingly candid. According to Runway, the most common failure is the robot reaching for an object that only resembles the target, and that mistake is usually already visible in the predicted video. Vague instructions work noticeably worse than ones that name colour or size. And multi-step tasks only work when each step gets its own instruction; chaining several steps from a single prompt remains hard. Runway suggests putting a language or vision-language model in front to break tasks into steps.
What it means for developers
Praxis-1 joins a wave of open models for physical AI. Just yesterday we covered MBZUAI’s PAN 2 world model, and in September Black Forest Labs released FLUX 3 Action, an open robotics model that Praxis-1 now measures itself against directly. Google takes the cloud route with Gemini Robotics-ER 2.
The real difference is the license: Apache 2.0 for weights and training code allows royalty-free commercial use and adaptation on your own hardware, including via LoRA. For robotics teams that previously had to train their own policies from scratch, that can shorten the path noticeably. Realistically, though, a new robot still needs its own data and compute, and a benchmark success rate of around 46 percent is far from reliable production use.
Runway also points to its role as a founding member of the Cosmos Coalition, through which the company and NVIDIA aim to advance open world models for physical AI.
Bottom line
Runway Praxis-1 is a serious open robotics model with a generous license, thorough documentation and honestly stated limits. The “top spot” claim only holds among world action models and open foundation models; LLM agents lead the same leaderboard by a wide margin. Anyone building robots should look at the base model and the fine-tuning code and verify the vendor’s numbers on their own hardware.